Batch APIs and off-peak pricing: cheaper AI for work that can wait
Most major providers offer about half-price processing for jobs that don’t need an instant answer. What qualifies, how it works and what to watch for.
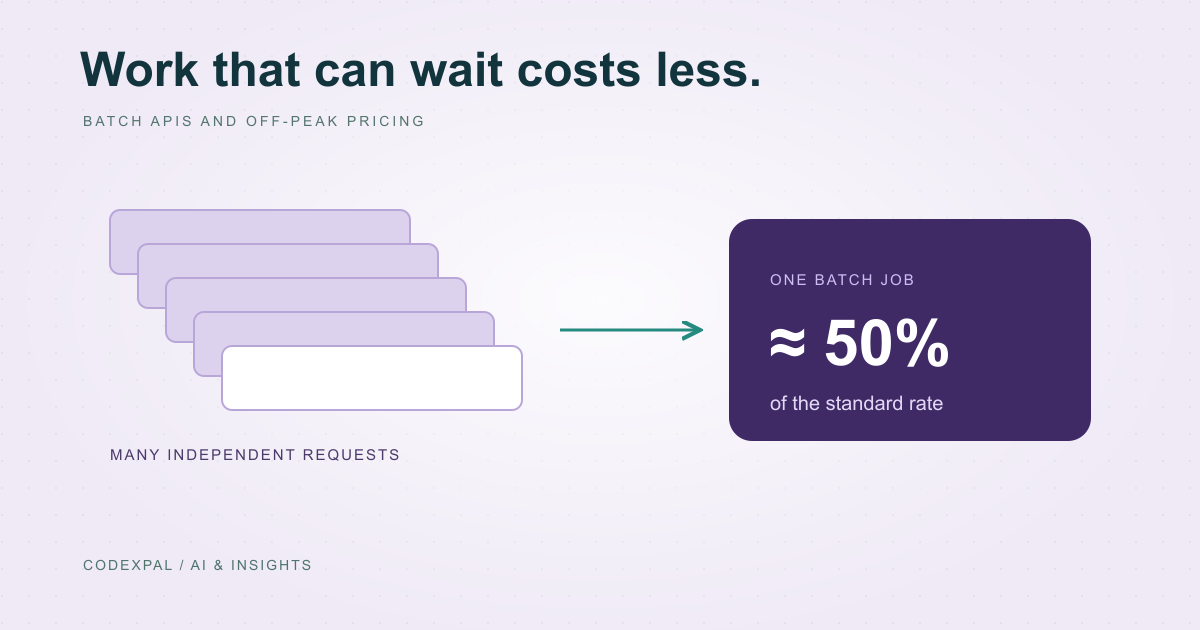
Not every AI task needs a response in seconds. Classifying a backlog of support tickets, extracting fields from documents, translating a product catalogue or running an evaluation set can all wait. Providers reward that flexibility with lower prices.
What each provider offers
OpenAI lists Batch and Flex prices at about half its Standard rates. Anthropic’s Batch API gives a 50% discount on input and output tokens. Google lists a 50% cost reduction for the Gemini Batch API. Mistral lists batch processing at a 50% reduction.
DeepSeek uses time of day instead: off-peak rates are half the peak rates. Its peak hours are 01:00–04:00 and 06:00–10:00 UTC, Monday to Friday, excluding Chinese public holidays.
Reference: OpenAI — API pricing · Anthropic — Claude API pricing · Google — Gemini API pricing · Mistral — pricing · DeepSeek — API models and pricing
How a batch job works
You prepare a file or list of independent requests, submit it, and collect results when processing finishes. Each request is still a normal model call; only the scheduling changes.
Design for asynchronous results. Store each request’s identifier, check job status, and handle requests that fail inside an otherwise successful batch.
Batch processing flow
- 01CollectIndependent requests with your own IDs
- 02SubmitOne batch job
- 03WaitProcessing completes asynchronously
- 04ReconcileMatch results to IDs; retry failures
Reference: Anthropic — batch processing
Good and poor fits
Good fits are large, independent jobs where a delay is acceptable: tagging, summarising archives, data extraction, nightly reports and model evaluations. Poor fits are anything a person is waiting for, and chained steps where each call depends on the previous answer.
| Workload | Batch or off-peak? | Why |
|---|---|---|
| Live chat or support replies | No | A person is waiting |
| Tagging 50,000 tickets | Yes | Independent and not urgent |
| Nightly document summaries | Yes | Fixed schedule |
| Multi-step agent | Usually no | Each step needs the last result |
| Evaluation test suite | Yes | Results needed later, in bulk |
Combine discounts carefully
Anthropic states that Batch API and prompt caching discounts can be combined. It also states that its faster output mode is not available with batch. Check each provider’s documentation for which features stack before assuming the lowest possible rate.
Open the AI API cost calculator →
Reference: Anthropic — Claude API pricing
The takeaway
Separate work that needs an instant answer from work that can wait. Moving the second group to batch or off-peak processing can roughly halve its cost with no change in model quality.
Sources & further reading
Primary references checked on November 12, 2026. Examples and diagrams are illustrative unless stated otherwise.
More to think about.
AI API pricing explained: tokens, caching, batch and long context
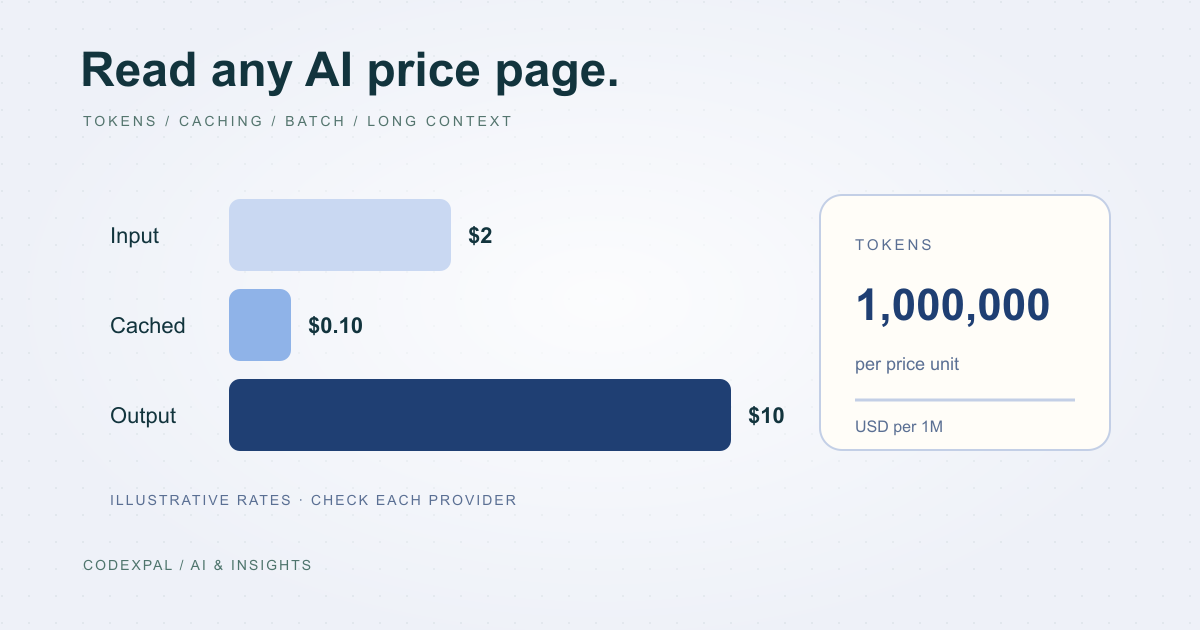
How OpenAI, Claude, Gemini, DeepSeek and Mistral charge for API use, why output costs more than input, and the four modifiers that change your real rate.
Prompt caching explained: when it cuts your AI bill and when it doesn’t
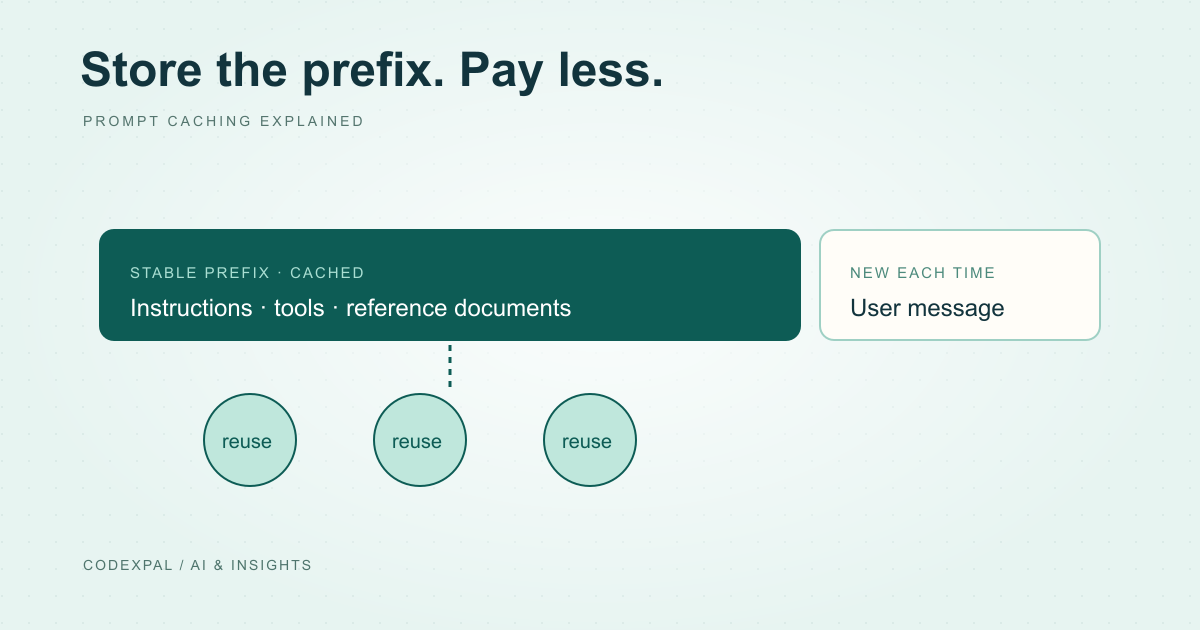
Cached input can cost a small fraction of normal input. Here is how OpenAI, Claude, Gemini and DeepSeek price caching, the break-even logic and how to structure prompts for it.